
Artificial intelligence models can provide textual answers to a wide range of questions, including medical questions. Recently, these models have incorporated the ability to interpret and answer image-based questions, and this includes radiological images. The main objective of this study is to analyse the performance of ChatGPT-4o compared to third-year medical students in a Radiology and Applied Physics in Medicine practical exam. We also intend to assess the capacity of ChatGPT to interpret medical images and answer related questions.
Materials and methodsThirty-three students set an exam of 10 questions on radiological and nuclear medicine images. Exactly the same exam in the same format was given to ChatGPT (version GPT-4) without prior training. The exam responses were evaluated by professors who were unaware of which exam corresponded to which respondent type. The Mann–Whitney U test was used to compare the results of the two groups.
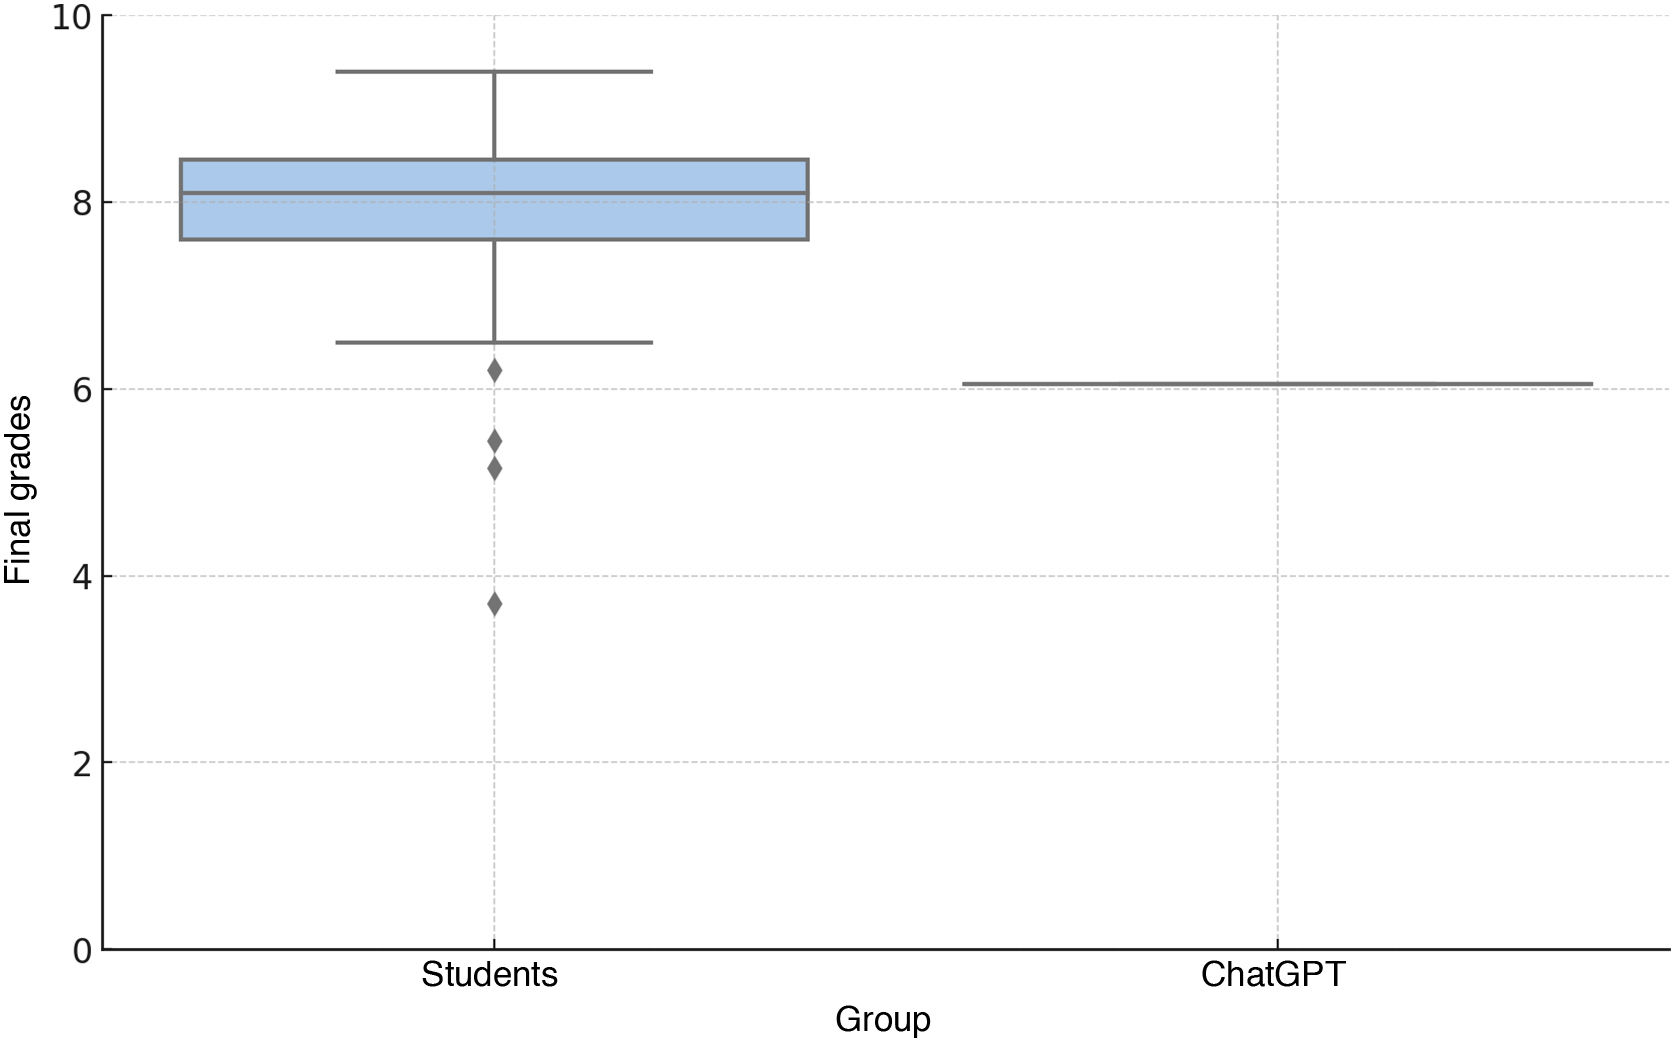
ResultsThe students outperformed ChatGPT on eight questions. The students’ average final score was 7.78, while ChatGPT’s was 6.05, placing it in the 9th percentile of the students’ grade distribution.
DiscussionChatGPT demonstrates competent performance in several areas, but students achieve better grades, especially in the interpretation of images and contextualised clinical reasoning, where students’ training and practical experience play an essential role. Improvements in AI models are still needed to achieve human-like capabilities in interpreting radiological images and integrating clinical information.
Los modelos de inteligencia artificial ofrecen la capacidad de generar respuestas textuales a una amplia variedad de preguntas, incluidas aquellas relacionadas con temas médicos. Recientemente, han incorporado la posibilidad de interpretar y responder a consultas basadas en imágenes, incluyendo imágenes radiológicas. El objetivo principal del estudio es analizar el rendimiento de ChatGPT-4o frente a estudiantes de tercer año de Medicina en una prueba práctica de la asignatura de Radiología y Medicina Física. Como objetivo secundario pretendemos valorar la capacidad de ChatGPT para interpretar imágenes médicas y responder a preguntas sobre las mismas.
Material y métodosSe examinó a un grupo de 33 estudiantes con 10 preguntas sobre imágenes radiológicas y de medicina nuclear. El mismo examen se administró a ChatGPT (versión GPT-4o) sin entrenamiento previo, siguiendo un formato idéntico. Las respuestas al examen fueron evaluadas por profesores que desconocían que examen correspondía al modelo a prueba. Se utilizó la prueba U de Mann-Whitney para comparar los resultados entre los dos grupos.
ResultadosLos estudiantes superaron a ChatGPT en ocho preguntas. La calificación media final de los estudiantes fue de 7,78 y la de ChatGPT fue de 6.05, situándose en el percentil 9 de la distribución de notas de los estudiantes.
DiscusiónChatGPT muestra un rendimiento competente en varias áreas, pero los estudiantes obtienen mejores calificaciones, especialmente en la interpretación de imágenes y en el razonamiento clínico contextualizado, donde la formación y la experiencia práctica de los estudiantes juega un papel esencial. Son necesarias todavía mejoras en los modelos de IA para alcanzar la capacidad humana de interpretar imágenes radiológicas e integrar información clínica.
The use and adoption of large-scale language models, such as ChatGPT, is unprecedented. This model, which uses artificial intelligence (AI) to generate contextualised responses based on training with millions of inputs, has the potential to transform various fields, including medicine and medical education, and is among the most discussed and commented on topics today due to its ability to revolutionise the way information is accessed and used in these fields.1,2
Four articles indexed in PubMed with the word ‘ChatGPT’ were published in 2022. In 2023, the number of publications increased significantly to 2082. As of 7 August 2024, 2261 articles had already been published that year.3
On 13 May 2024, the latest iteration of ChatGPT, version 4-Omni (GPT-4o), was released, representing a significant advancement over previous models by integrating multimodal capabilities which enable results to be managed and generated from text, audio and images.4,5 GTP-4o improves response speed and efficiency, and enhances capabilities in languages other than English. Previous models could interpret images from text inputs describing them, until the GPT-4V version came out in September 2023, with the V standing for its visual ability to interpret images, including radiological images.6 However, the latest version features improved accuracy in radiological image interpretation, with faster responses and the ability to interpret images from photos or screenshots from different devices. Its utility and performance have already been assessed in medical examinations, but only performance has been studied in reasoning or multiple-choice questions based on clinical cases, without medical images.7–13
In our institution's undergraduate medical programme, students take Radiology and Physical Medicine in the third year of their six-year course. They receive theoretical classes and practical seminars, and complete internships supervised by the hospital's Radiology, Nuclear Medicine, Radiotherapy and Rehabilitation departments. They are then assessed with a practical and a theoretical test. In the practical exam, they have to answer short questions about images shown to them (Appendix A Supplementary material).
We put ChatGPT's ability to interpret and answer questions based on medical images to the test against students' training and practical knowledge.
The objectives of the study were to evaluate the accuracy of ChatGPT in interpreting radiological and nuclear medicine images and to compare ChatGPT's responsiveness with that of medical students on image interpretation questions.
Material and methodsWe conducted a comparative study on a group of 37 third-year students studying Radiology and Physical Medicine at the University of Barcelona. This study was approved by the Independent Ethics Committee for Research with Medicines of Hospital Clínic de Barcelona.
StudentsThe 37 students were part of the second group out of the total of 77 students enrolled in the second semester of the course. This was the last group to be routinely assessed on the subject. They were assessed at the end of their practical and theoretical sessions for the subject, before the final theoretical exam. At the end of the exam, they were informed about the study and asked for informed consent to participate in it. Thirty-three of the students gave their consent, making them the only ones included in the comparison.
Practical examAs part of their practical assessment, they were asked 10 questions which included the description and interpretation of radiological and nuclear medicine images, and the description of physical medicine equipment. The questions were posed by the same lecturers who had given the practical exercises for the subject. The exam contained seven radiology questions, from different areas, numbered from 1 to 7 in this order: chest (X-ray); neuro (CT); breast (mammography); musculoskeletal (X-ray); genitourinary (ultrasound and CT); and two abdomen (CT and MRI). Two questions were about nuclear medicine (ventilation-perfusion scintigraphy and PET-CT) and the last one was about radiotherapy (radiotherapy devices).
We did not record the time spent by each student on each question.
Taking the examThe 10 questions were presented in a classroom one by one as slides and the students had 5 min to answer each question, without being able to go back in the presentation.
The night before the students were to be tested, the same test was administered to GPT-4o, without prior training. The 10 questions were presented in the same format used for the students; each question was displayed on a slide with the image and the associated questions.
The version used for the study is the one technically known as GPT-4 Turbo (2023), with content updates until the end of 2023.
The prompt with the instructions it had to follow in order to answer was as follows: “You are a medical student and you need to answer the following questions from a practical exam in Radiology and General Physical Medicine. You must provide short answers to the questions that appear in text based on the images provided on the same slide. You can answer in Spanish or Catalan. Answers should be very short, without description or explanation unless requested. You should try to get the best grade possible”.
It was then asked to indicate how long it would take it to answer each question if it were a medical student and how long it took it to process each question as an AI.
The answer to each question was transferred at the time of the exam to an answer sheet, handwritten by one of the authors, copying without modification the text generated by the application and with false information about the student's identification number and name.
Exam evaluationThe exams were marked by the lecturers, of whom eight out of 10 were not aware of the study being conducted, and the other two consciously avoided any bias in their marking and did not know which exam was answered by the GPT-4o model. Each question was scored from 0 to 1, with no possibility of negative evaluation. The final grade was the sum of the scores for each of the 10 questions, with a score of 5 or higher indicating a pass. The final grade for the subject for students gives a weight of 40% to the score of the practical exam evaluated in this study.
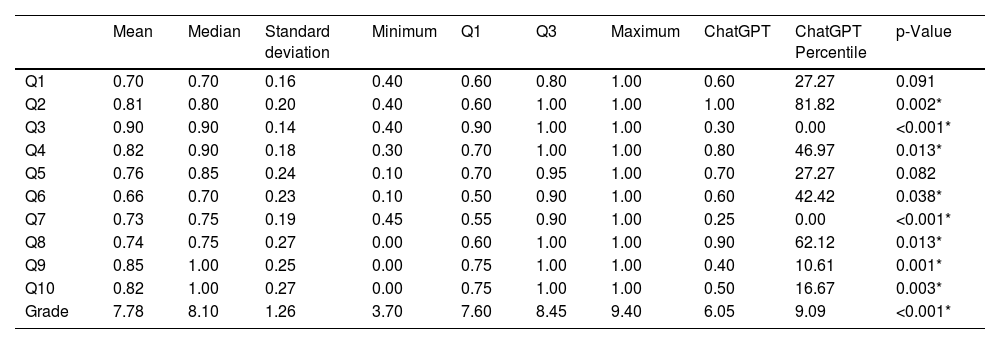
Statistical analysisA descriptive analysis of the results was carried out using measures of central tendency and dispersion, which are shown in Table 1, comparing the results of the student group with that of ChatGPT, evaluating the results for each question, as well as for the final grade. The percentile to which the ChatGPT response corresponded with respect to the students' responses was obtained.
Summary of results for each question.
| Mean | Median | Standard deviation | Minimum | Q1 | Q3 | Maximum | ChatGPT | ChatGPT Percentile | p-Value | |
|---|---|---|---|---|---|---|---|---|---|---|
| Q1 | 0.70 | 0.70 | 0.16 | 0.40 | 0.60 | 0.80 | 1.00 | 0.60 | 27.27 | 0.091 |
| Q2 | 0.81 | 0.80 | 0.20 | 0.40 | 0.60 | 1.00 | 1.00 | 1.00 | 81.82 | 0.002* |
| Q3 | 0.90 | 0.90 | 0.14 | 0.40 | 0.90 | 1.00 | 1.00 | 0.30 | 0.00 | <0.001* |
| Q4 | 0.82 | 0.90 | 0.18 | 0.30 | 0.70 | 1.00 | 1.00 | 0.80 | 46.97 | 0.013* |
| Q5 | 0.76 | 0.85 | 0.24 | 0.10 | 0.70 | 0.95 | 1.00 | 0.70 | 27.27 | 0.082 |
| Q6 | 0.66 | 0.70 | 0.23 | 0.10 | 0.50 | 0.90 | 1.00 | 0.60 | 42.42 | 0.038* |
| Q7 | 0.73 | 0.75 | 0.19 | 0.45 | 0.55 | 0.90 | 1.00 | 0.25 | 0.00 | <0.001* |
| Q8 | 0.74 | 0.75 | 0.27 | 0.00 | 0.60 | 1.00 | 1.00 | 0.90 | 62.12 | 0.013* |
| Q9 | 0.85 | 1.00 | 0.25 | 0.00 | 0.75 | 1.00 | 1.00 | 0.40 | 10.61 | 0.001* |
| Q10 | 0.82 | 1.00 | 0.27 | 0.00 | 0.75 | 1.00 | 1.00 | 0.50 | 16.67 | 0.003* |
| Grade | 7.78 | 8.10 | 1.26 | 3.70 | 7.60 | 8.45 | 9.40 | 6.05 | 9.09 | <0.001* |
Q1–Q10: questions 1–10; Q1: quartile 1; Q3: quartile 3.
For statistical analysis, the Mann–Whitney U test was used, a non-parametric statistical test used to evaluate whether there is a significant difference between the distributions of two independent groups. We selected this test due to the nature of the data, the small sample size, the asymmetry in the size of the student group (33) with ChatGPT (one) and the need to compare two independent groups (ChatGPT and students).
We performed the statistical analysis using Python version 3.9 (Python Software Foundation) with the SciPy library version 1.7.3,14 which provides consistent functions for performing non-parametric statistical tests.14 A p-value <0.05 was considered to indicate a statistically significant difference.
We obtained descriptive and statistical analysis and graphics by co-piloting with ChatGPT-4o.
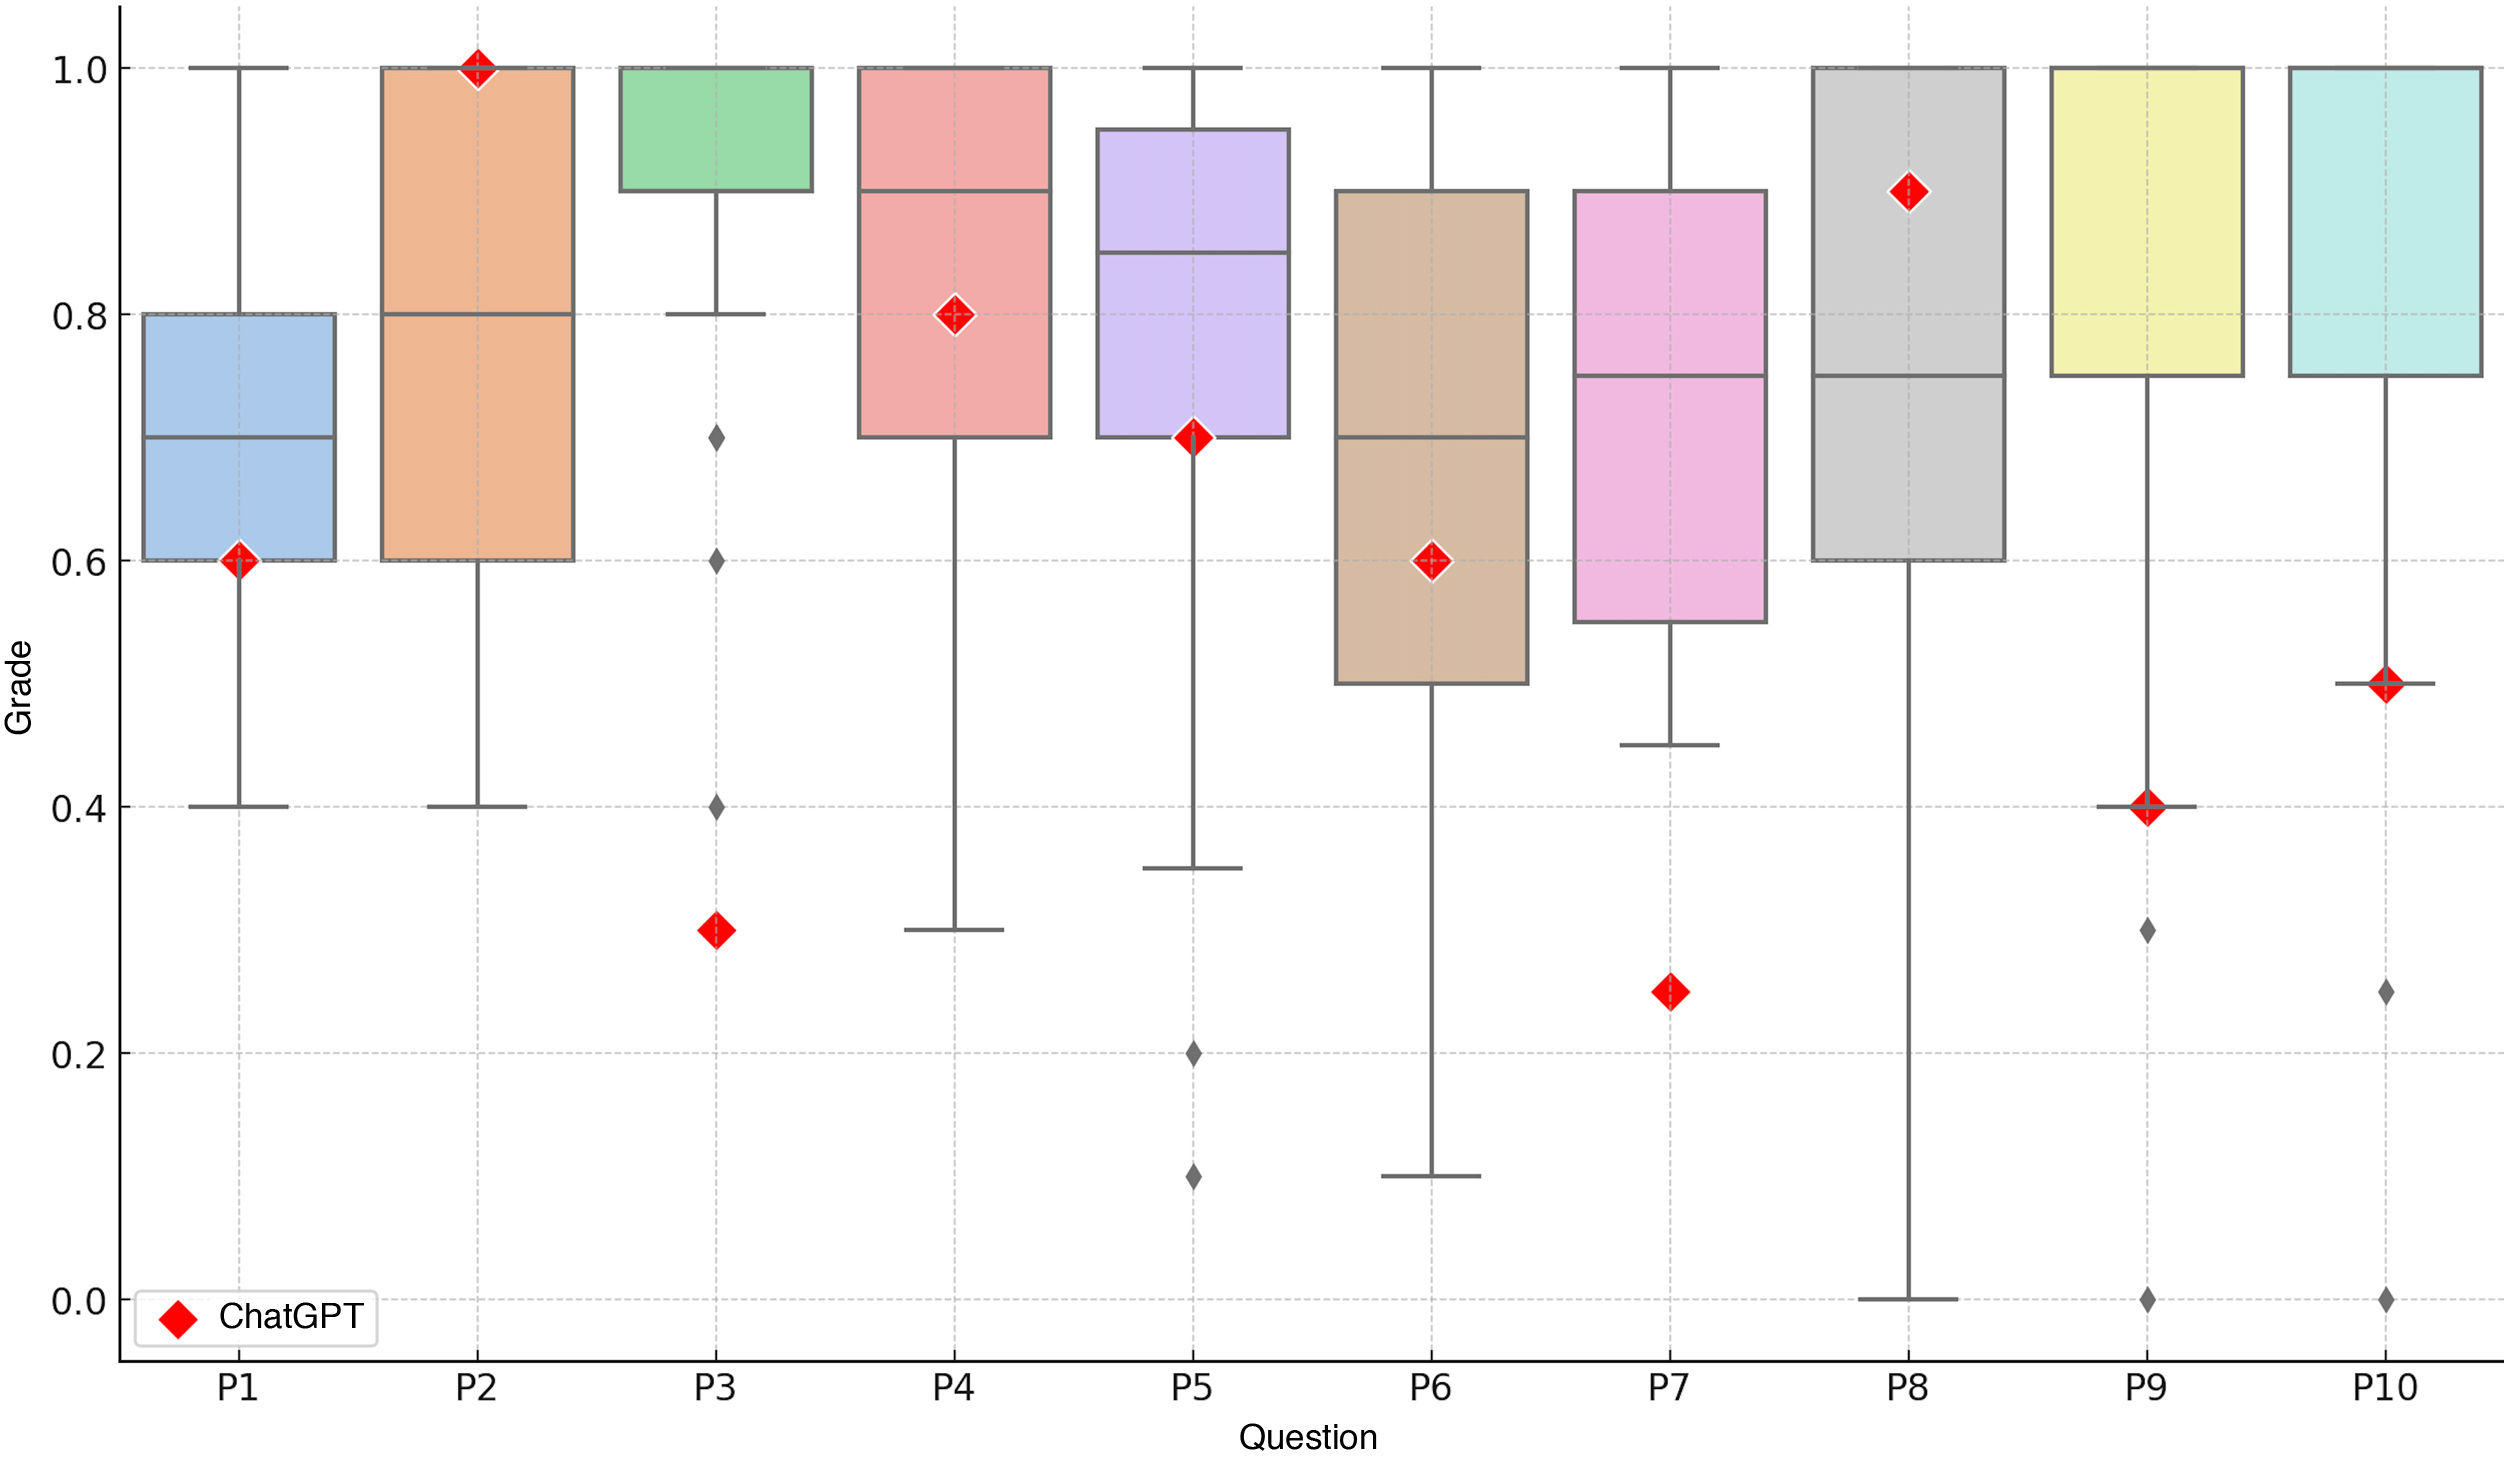
ResultsThe results are shown in Table 1 and graphically in Figs. 1 and 2 with boxplot distribution boxes for the students' responses and the value of the model's response.


Students demonstrated greater ability to interpret complex radiological images, outperforming ChatGPT on most questions related to this area.
The results show statistically significant differences both in the final grade and in most of the questions (Fig. 3), except for questions 1 and 5.

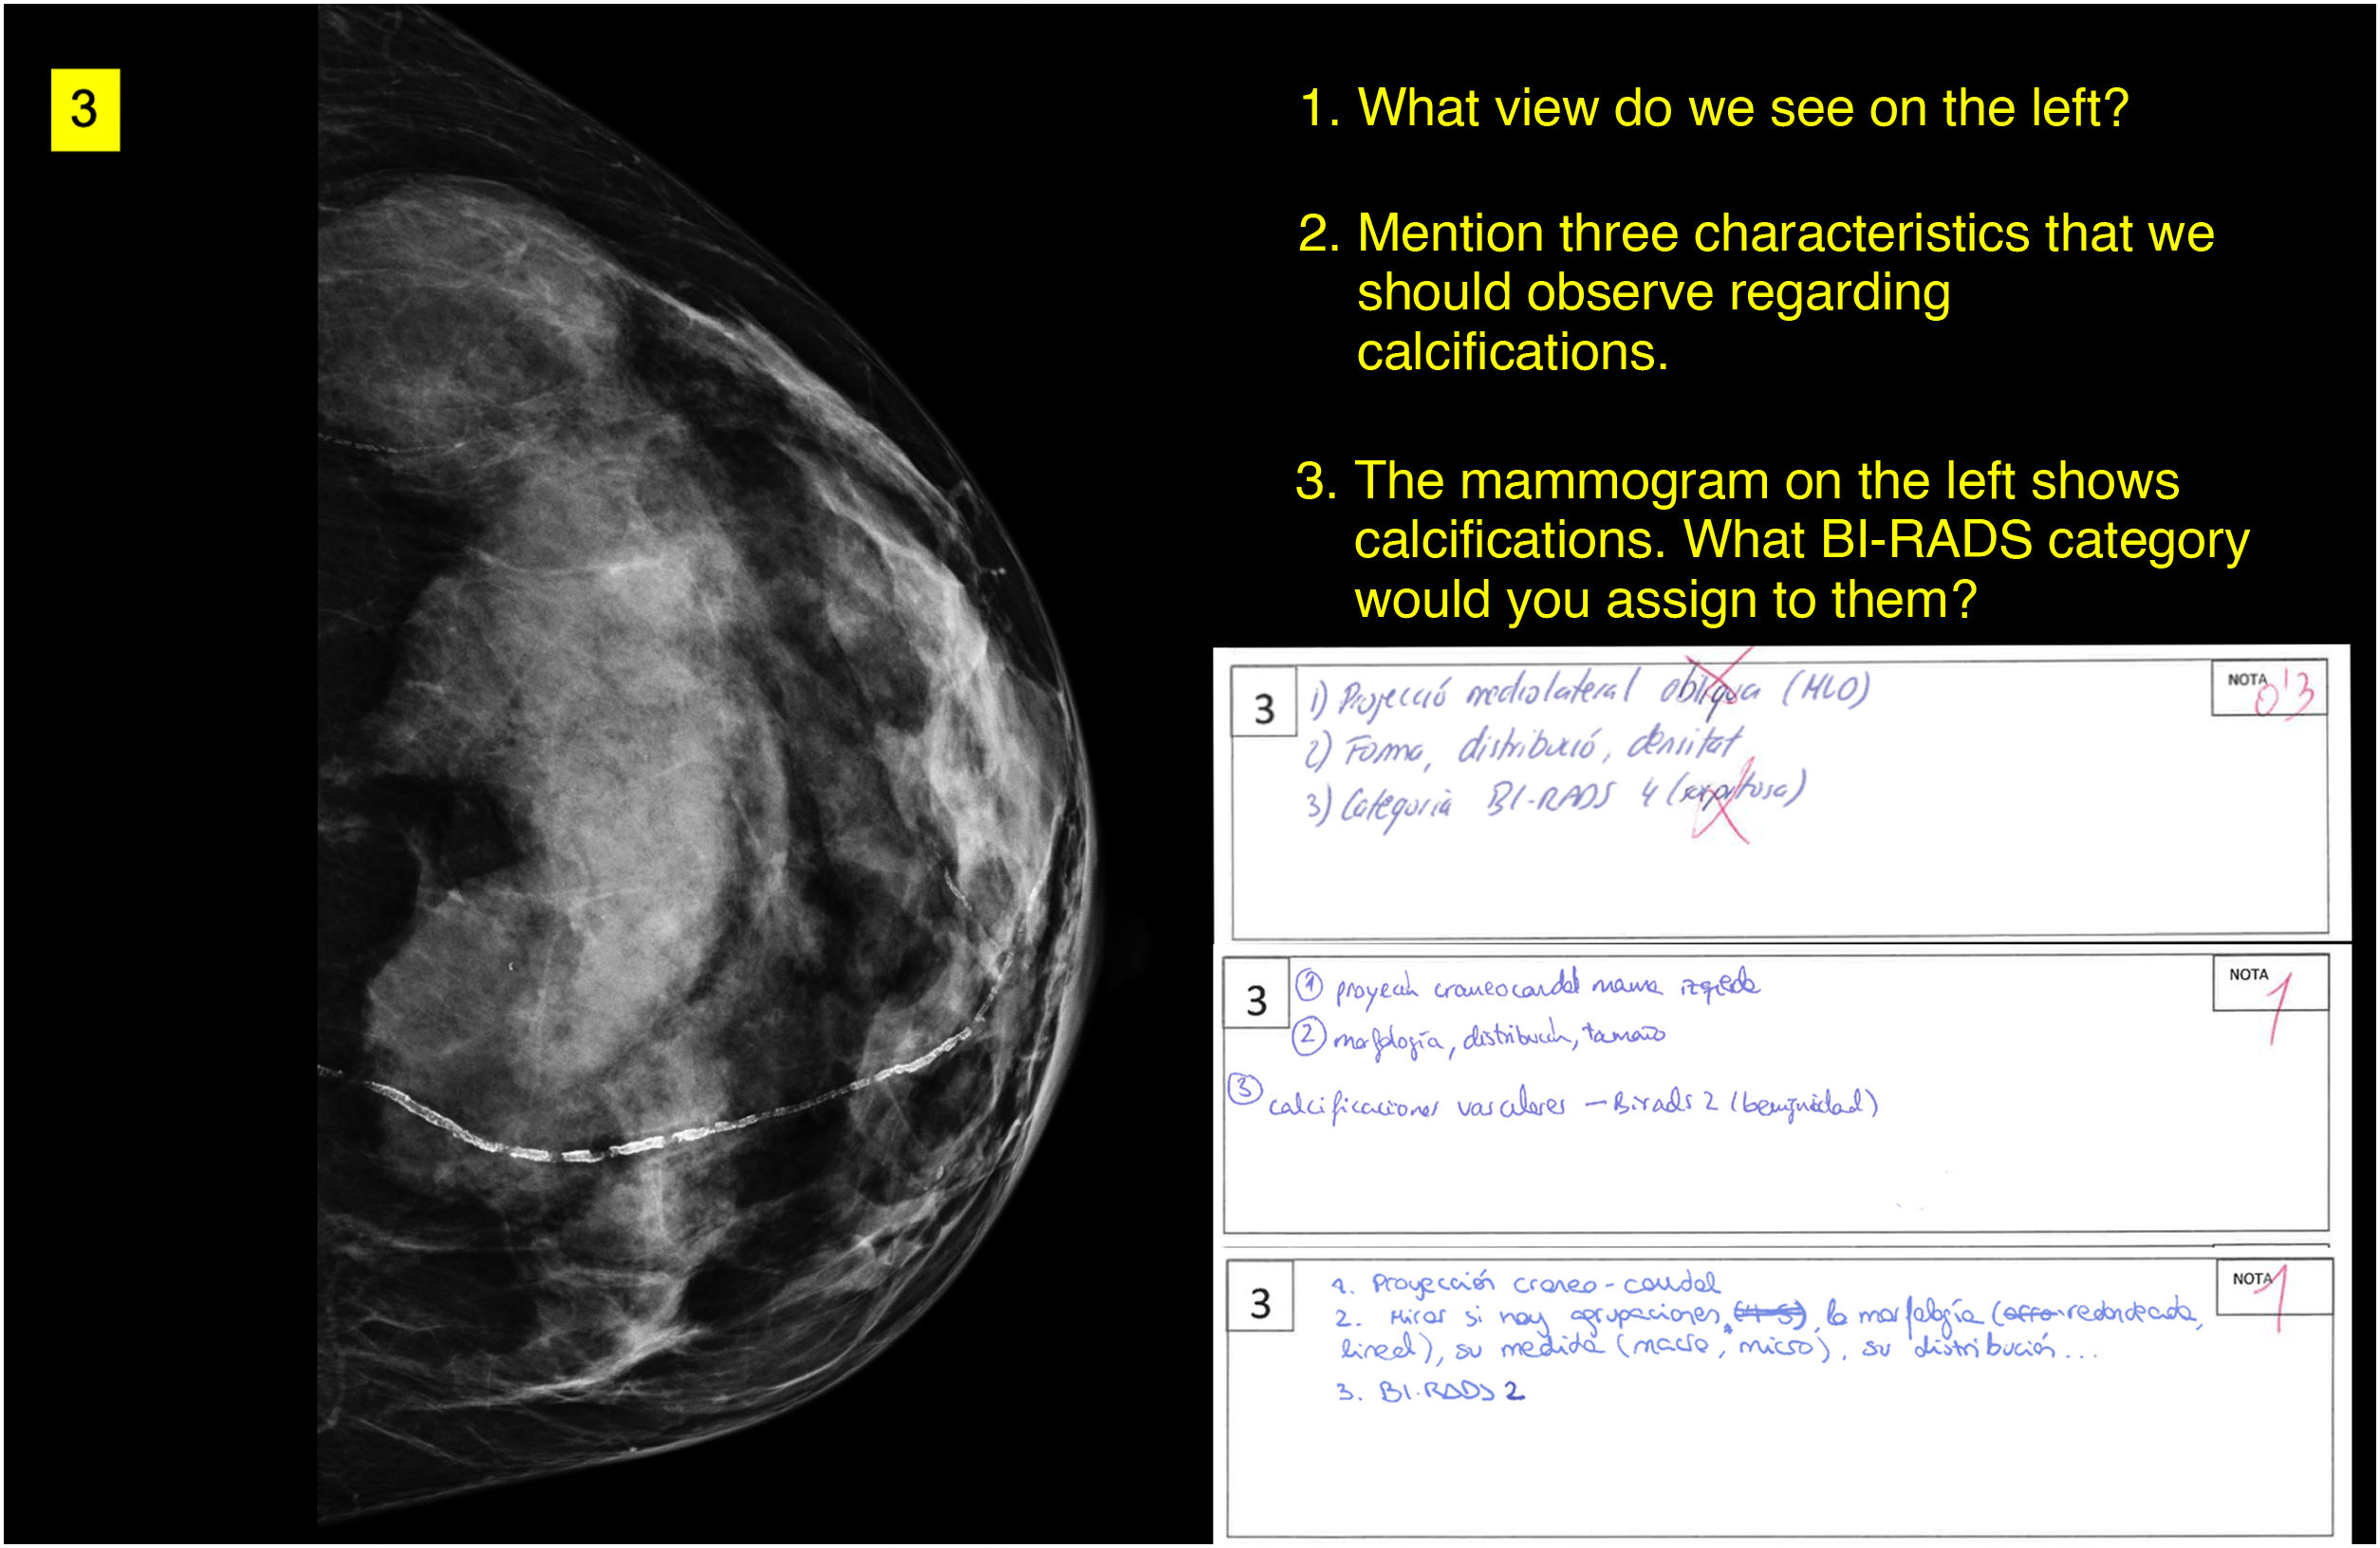
Example of question and answers. Corresponds to question 3, a craniocaudal mammography image with BI-RADS 2 benign vascular calcifications. The model, the first of the three answers shown, failed to identify the view, and was mistaken in the interpretation of the calcifications, which it assigned a BI-RADS 4, and earned 0.3 out of a maximum of 1 point. The other two responses shown, from students, obtained the maximum score of 1.
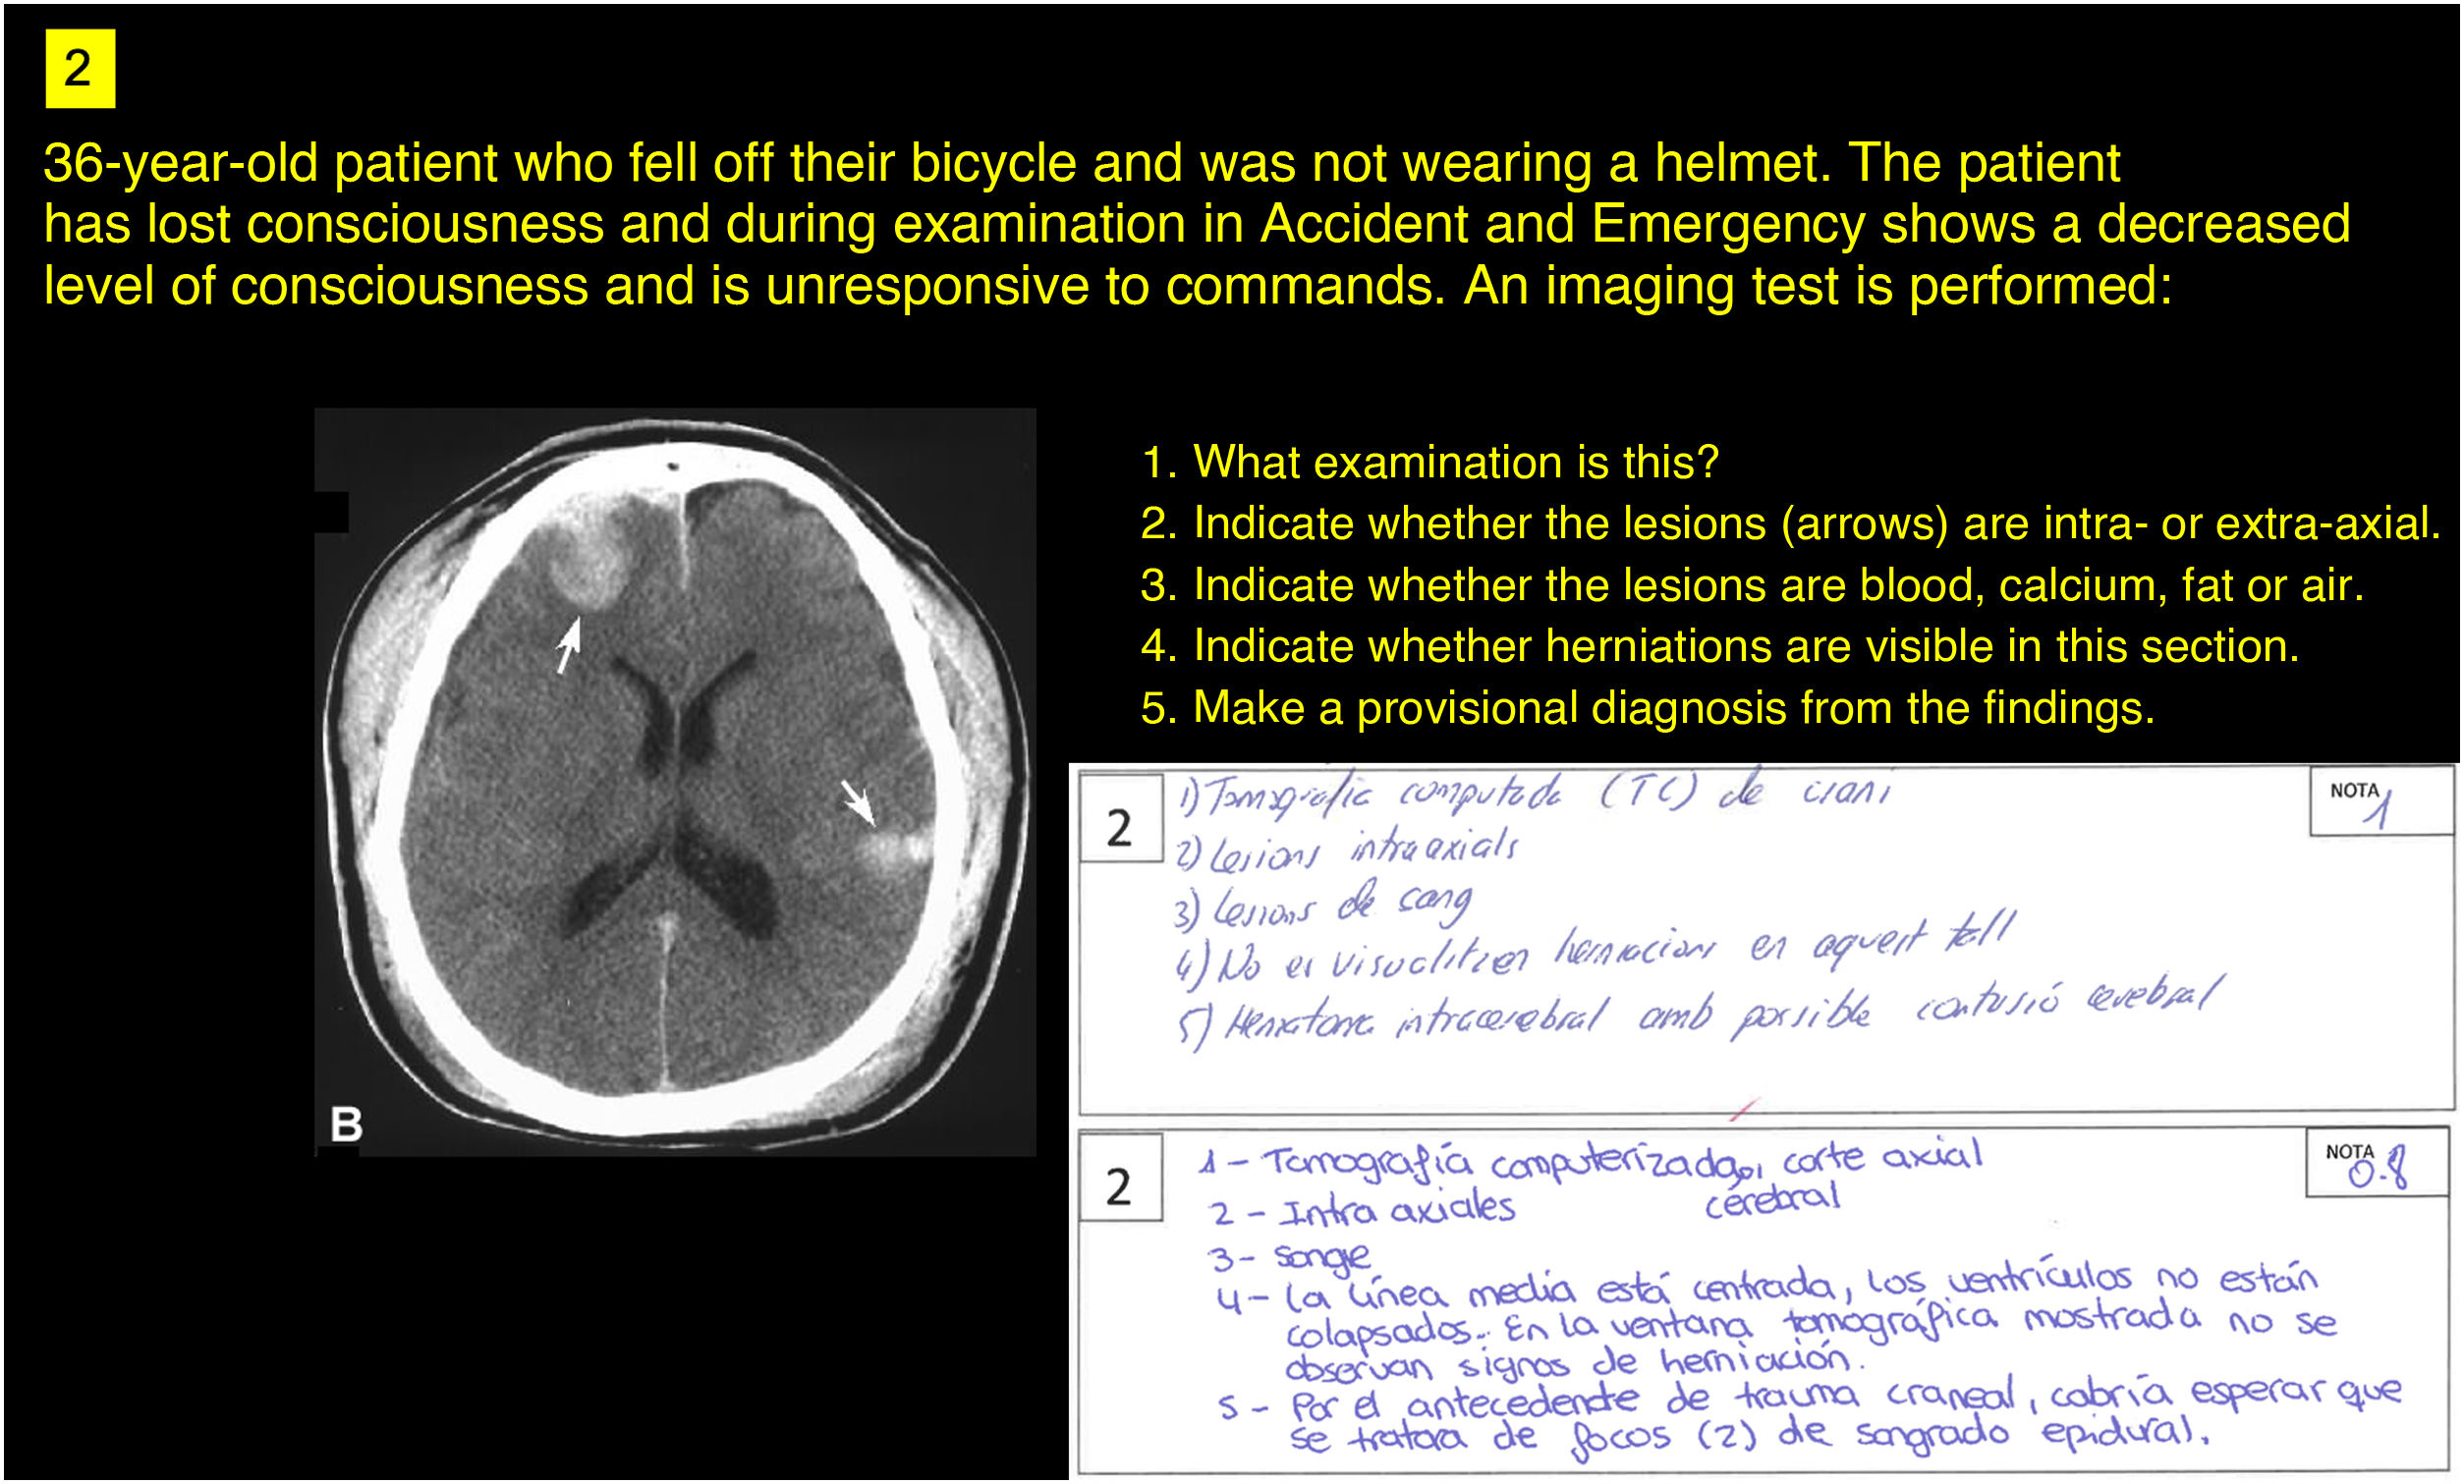
The GPT-4o model surpassed the students in only two questions: in question 2, on extra-axial bleeding in a brain CT, where it obtained the maximum score (Fig. 4); and in question 8, on the identification and interpretation of a ventilation-perfusion scan.

Example of question and answers. Question 2 presented a 36-year-old patient with head trauma and neurological impairment from a fall off a bicycle with no helmet. The model (first answer) obtained the maximum score by correctly answering everything requested. The second answer, from a student, incorrectly specified the type of indentation in the last of the five questions, earning 0.8 points for the sum of the other four correct answers.
Although the model's final grade would have allowed it to pass, it only surpassed three students, placing it in the 9th percentile of the distribution of student grades.
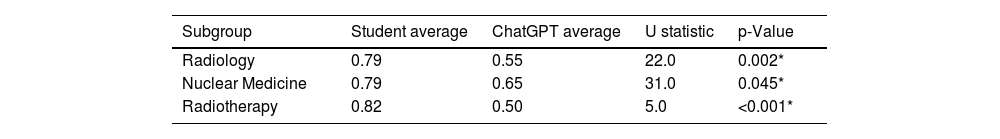
By areas of knowledge, the comparison is shown in Table 2.
The scores obtained in all areas by ChatGTP were lower than those of the students, reaching statistical significance. The greatest differences were obtained in radiology and radiotherapy.
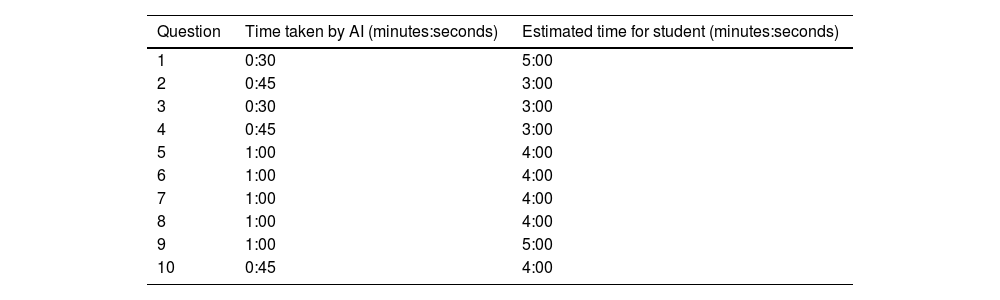
The time spent by ChatGPT to answer the questions, its estimation as a medical student and the time spent analysing and answering each question are shown in Table 3.
Time taken by the AI to answer and the time the AI estimates a student would take for each question.
| Question | Time taken by AI (minutes:seconds) | Estimated time for student (minutes:seconds) |
|---|---|---|
| 1 | 0:30 | 5:00 |
| 2 | 0:45 | 3:00 |
| 3 | 0:30 | 3:00 |
| 4 | 0:45 | 3:00 |
| 5 | 1:00 | 4:00 |
| 6 | 1:00 | 4:00 |
| 7 | 1:00 | 4:00 |
| 8 | 1:00 | 4:00 |
| 9 | 1:00 | 5:00 |
| 10 | 0:45 | 4:00 |
Students had 5 min to answer each question and did not leave any answers blank or incomplete, but the time spent by each student in answering each question was not analysed.
DiscussionThe results indicate that ChatGPT performs adequately in interpreting images to provide answers to questions about radiology and nuclear medicine, which would result in a pass grade. Although it performed well on some questions, especially those requiring precise technical information, its ability to interpret images and contextualise answers in a clinical setting was limited and inferior compared to the students. ChatGPT, while showing a reasonable ability to interpret images based on available textual information, lacks the clinical experience and context needed to match the level of students in this area. This highlights a major limitation of AI models: a lack of practical experience and a limited ability to contextualise information in complex clinical settings.
Each new version or iteration of this generative AI model provides improved performance due to deeper, more specific learning. Particularly in the field of medical education, the GPT-4 version provided a performance of 94%, which is markedly superior to its previous version, which obtained 66% correct answers to MIR questions in the subject of Rheumatology.7
Interpreting radiology or nuclear medicine questions that may involve medical images, however, goes beyond analysing a clinical situation based on text data and laboratory test values, requiring a higher level of data interpretation and clinical contextualisation. In fact, ChatGPT's performance on non-image questions from the United States Board of Radiology examination was high for simple questions (84% correct answers), but moderate for those requiring the description of findings (60%) and low to calculate and classify (25%) or in the application of radiological concepts (30%).15 The previous model, GPT-4V, which can interpret images, also has limitations in the ability to interpret abnormal findings on plain chest films.16
In its latest version, which is the one used in this study, GPT-4o has been trained with a huge amount of textual and visual data, including data from books, articles, websites and other public and licensed sources. The data used is estimated to cover several petabits (1024 terabits) of information, which represents a significant increase compared to previous versions such as GPT-3 and GPT-4. Although exact figures on the number of radiological images used have not been released, the scale of data employed is considerable. GPT-4o is known to have extensively analysed medical images, including X-rays, CT scans, MRI and other medical imaging modalities to enhance its analytical and diagnostic capabilities in clinical settings. As the model itself explains, during GPT-40 training, special emphasis was placed on improving the model's ability to interpret and generate accurate responses from complex medical images. This includes tasks such as generating radiology reports, answering medical visual questions, and identifying anatomical and abnormal features in medical images.17
However, when analysing our results, we observed that the model mistook the side of the body of the most important finding in two of the questions. The errors made in our study include: failure to identify vascular calcifications or the type of projection in a mammogram image; incorrect interpretation of the side of a thoracic lesion on an X-ray or of a bladder mass with ureterohydronephrosis in an ultrasound and CT image; and lastly, confusion of a T2-weighted axial liver MRI image with a T1-weighted image with contrast, and confusion in the identification of the large vessels in the same image. There are errors which, having received feedback after correction, will likely be fixed in a future version.
In an analysis of articles which have evaluated the performance of ChatGPT in radiology, 84% report high performance with an average accuracy of 70%, and when studies compare accuracy between versions 3.5 and 4, a significant improvement between versions was identified in understanding radiological terms and describing findings.18
The utility of ChatGPT for self-study as an assistant for resolving doubts, generating questions for exam preparation, or obtaining reasoned answers to previous questions means that many students are increasingly using these models to improve their learning and achieve better results. Our study reveals that AI estimates that a student could answer all questions within the set time, and this would enable teachers to assess a priori whether their questions can be answered by students within the established time limit.
Limitations of the study include the fact that the student sample was relatively small and not necessarily representative of the general student population, that two of the 10 examiners were not blinded to the study, and that the analysis was conducted on 10 highly fragmented questions that may not be representative of the entire subject, which could limit the generalisability of the results. It is worth noting that the AI model lacked specific training and that, in contrast, the questions were asked by the same lecturers who taught the exercises and had trained and coached the students.
The potential of generative AI models is undeniable. Currently, in the interpretation of radiological images and clinical contextualisation, medical students have a significant advantage over GPT-4. However, because GPT-4 is a new tool, its use is expanding rapidly and its capacity for improvement is continuous and rapid. This suggests that it will be useful as a supplementary tool both for learning among medical students and radiology residents and for the professional practice of radiologists.
ConclusionsChatGPT represents a promising tool for supporting medical image interpretation, although it cannot yet match human skill in complex clinical situations. The continued evolution and improvement of models like ChatGPT show great potential as a support tool in clinical and educational practice.
CRediT authorship contribution statement- 1
Responsible for the integrity of the study: RS.
- 2
Study conception: RS, XS, LO and CN.
- 3
Study design: RS, XS, LO and CN.
- 4
Data collection: RS, XS, LO and CN.
- 5
Data analysis and interpretation: RS, XS, LO and CN.
- 6
Statistical processing: RS.
- 7
Literature search: RS and MMG.
- 8
Drafting of the article: RS, LO and CN.
- 9
Critical review of the manuscript with intellectually relevant contributions: RS, DV, LO, MMG, ACF, XS and CN.
- 10
Approval of the final version: RS, DV, LO, MMG, ACF, XS and CN.
During the preparation of this work the authors used GPT-4o as an object of study and for statistical analysis. After using this tool, the authors reviewed and edited the content as needed, assuming full responsibility for the content of the publication.
FundingThis study received no specific grants from public agencies, the commercial sector or non-profit organisations.
The authors declare that they have no conflicts of interest.
The following is Supplementary data to this article: